Compare · SiteOps vs Better Stack
A Better Stack alternative priced for agencies, not on-call teams.
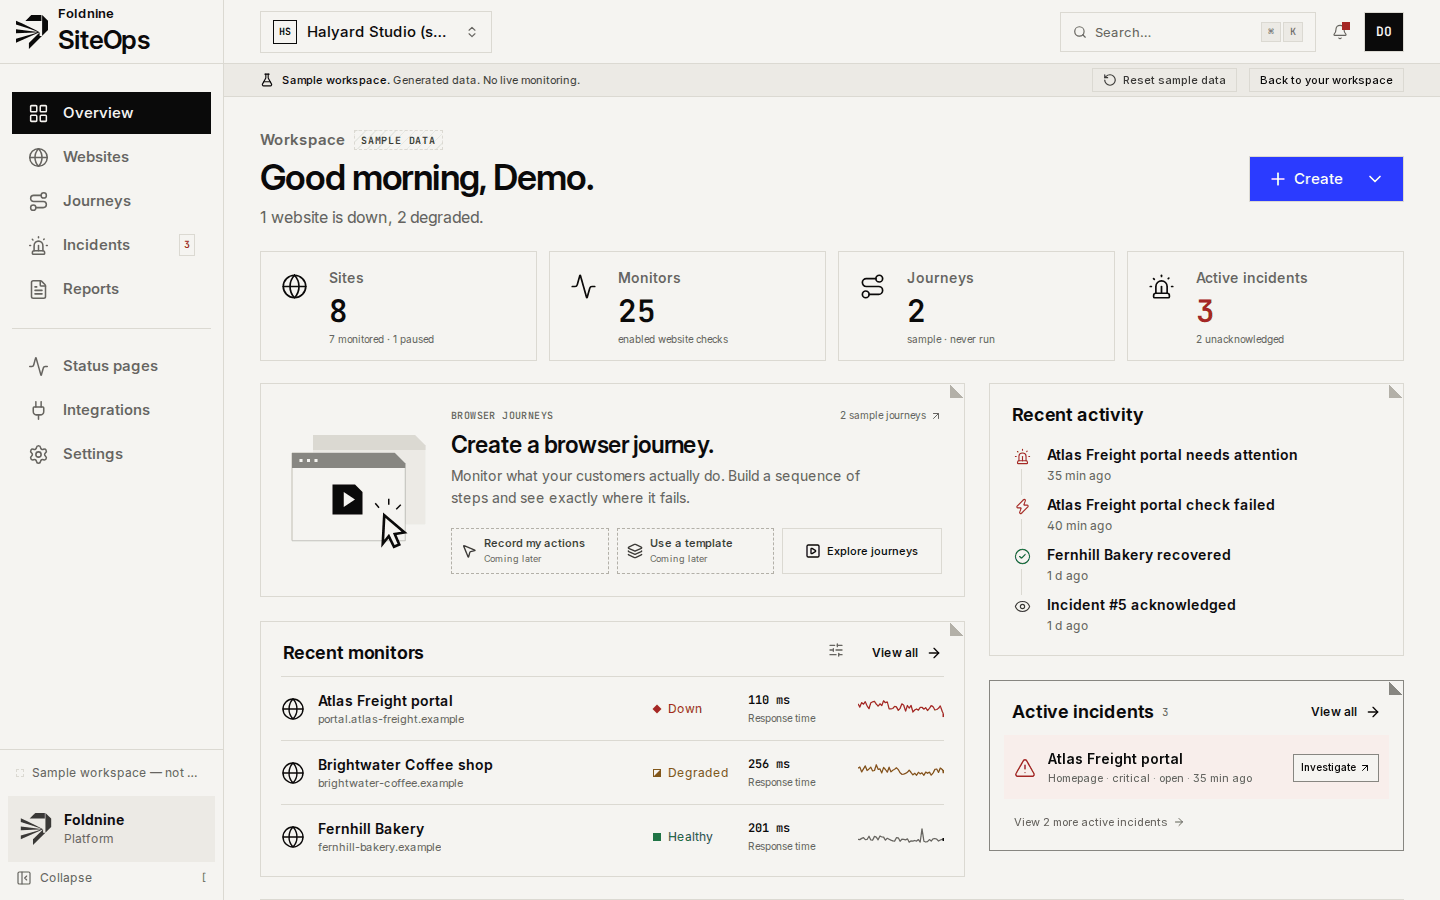
Better Stack Uptime is built for engineering teams on call: phone alerts, schedules, 30-second checks and logs next to it. SiteOps is built for agencies with many client sites, at a flat price per site with white-label included. Different jobs; here is where each is stronger.
The short answer
Which one fits you
Choose Better Stack if
- You run on-call rotations and need phone-call and SMS alerts, escalation policies and incident workflows.
- You need 30-second checks, heartbeats for cron jobs, mail-server checks or logs and telemetry in one place.
- You want status pages on your own subdomain.
Choose SiteOps if
- You look after many client sites and want one flat price: €69 a month for 100 sites, white-label included.
- You want branded client reports and status pages without a $250-per-page white-label add-on.
- You want broken-link checks and an incident link you can forward to a client.
Side by side
SiteOps and Better Stack, feature by feature
Better Stack's plans and features as published on its own site, read on 26 October 2026; prices in its currency. Check the pricing and Uptime pages before deciding; they change.
| Topic | SiteOps | Better Stack | Ahead |
|---|---|---|---|
| Price | Free (5 sites); Studio €29/mo (30 sites); Agency €69/mo (100 sites). Priced per website, not per check | Free tier; responder seat $34/mo ($29 yearly); extra 50 monitors $25/mo; extra status page $15/mo; status page white-label $250/mo per page | SiteOps |
| Free plan | 5 websites, checks every 5 minutes, email alerts, no card | 10 monitors and 10 heartbeats, 3-minute checks, 1 status page, Slack and email alerts | Better Stack |
| Fastest interval | 1 minute on Studio and Agency; 5 minutes on Free | 30 seconds | Better Stack |
| Check types | HTTP and response time, SSL certificate, DNS, read-only API (GET/HEAD with status and body assertions), broken links | HTTP, keyword, SSL, DNS, domain, ping, TCP, POP3, IMAP, SMTP, cron and heartbeats, Playwright | Better Stack |
| Broken links | Same-site links on a page | Not offered | SiteOps |
| Browser checks | Browser journeys (open, click, fill, assert, screenshot) on Agency, every 15 minutes at most | Playwright transaction checks, $1 per 100 minutes of run time | Better Stack |
| Locations | One location (Germany); failures are re-checked from the Cloudflare edge before an incident opens. Not continuous multi-region | Multiple locations with multi-step verification | Better Stack |
| Alerts and on-call | Email, Telegram, Slack and signed webhooks. No SMS or phone calls | Email, Slack, Teams, Telegram, webhook, SMS and phone calls; on-call schedules and escalation | Better Stack |
| Status pages | Client status pages on Studio and up; white-label on Agency. Hosted on siteops.foldnine.dev, no custom domain yet | Custom subdomain included; white-label $250/mo per page | Even |
| Client reports | Monthly client report by email, per client, on the day you choose; white-label on Agency | Reporting and analytics add-on for the team; no scheduled client reports | SiteOps |
| Incident detail | Incidents keep the evidence (status, headers, timings, certificate, DNS) and list facts apart from unverified causes; a read-only link you can send the client | Incident management with a timeline (we did not test its incident view) | Even |
When something fails
An incident you can forward without rewriting.
01A check fails twice
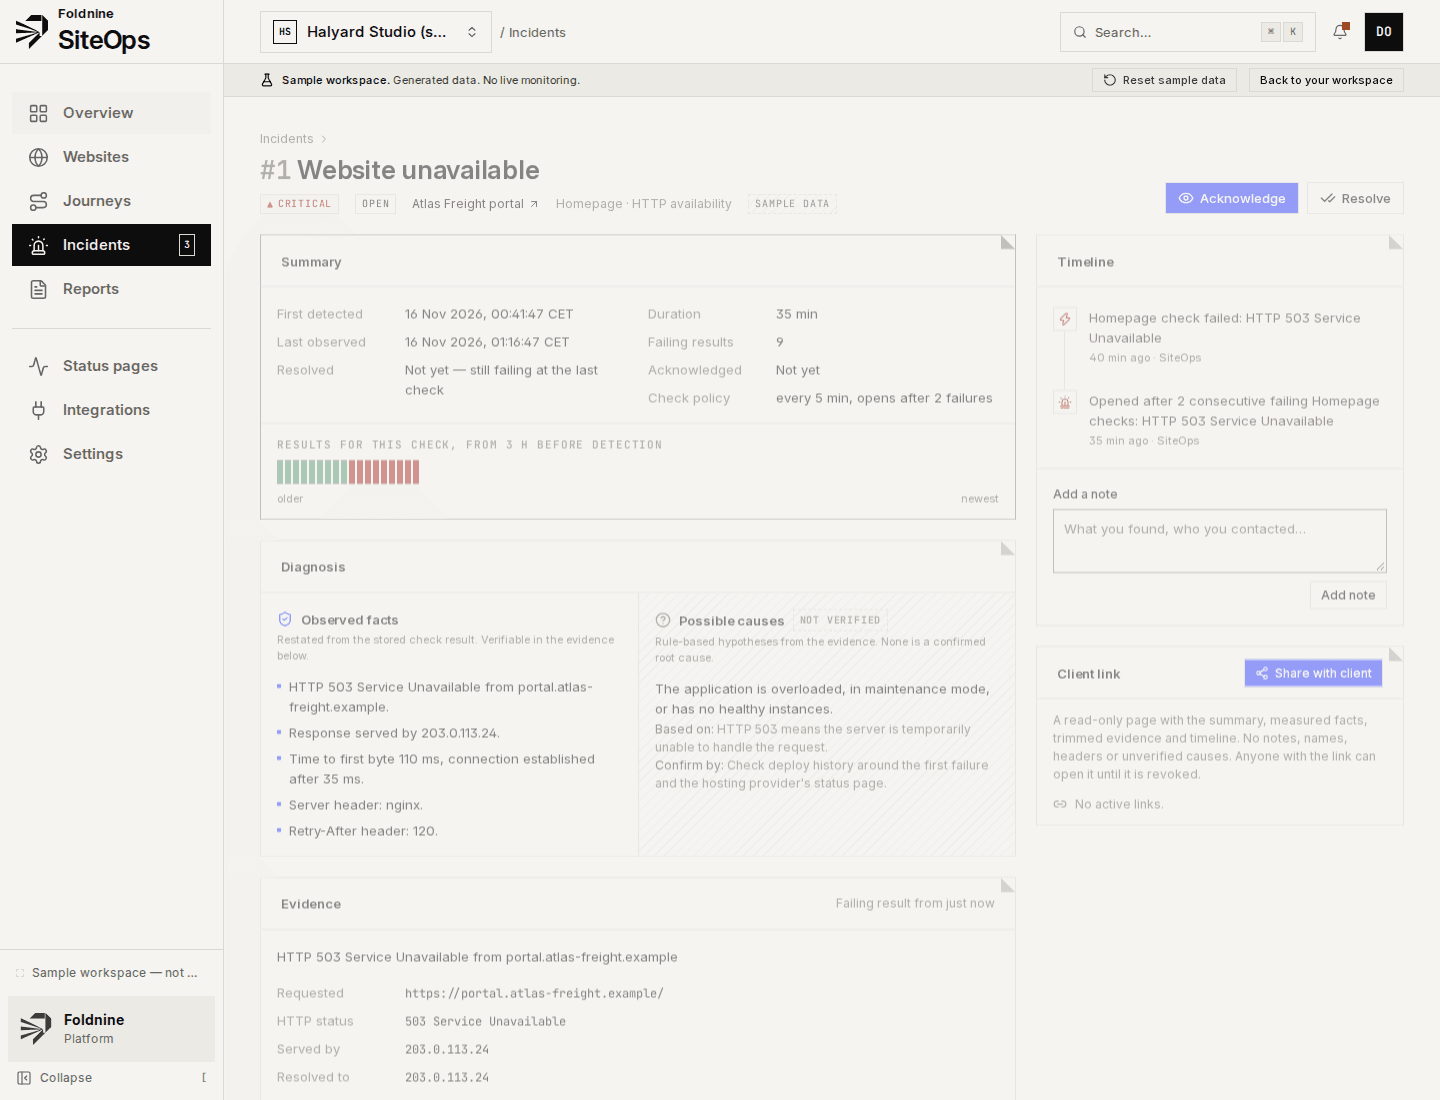
One bad result is noise. Two consecutive failures of the same check open an incident — threshold adjustable per check.
02Evidence is kept
HTTP status, response headers, body excerpt, resolved and serving address, TLS certificate, and where the time went.
03Facts apart from guesses
What was measured is listed as fact. Likely causes are labelled as unverified, each with what it rests on and how to confirm it.
04Recovery closes it
The first passing result resolves the incident and records how long it lasted. Notes and acknowledgements stay on the timeline.
Said plainly
Where SiteOps is weaker than Better Stack
Better to read it here than find out after you have moved your client sites.
- No on-call schedules, escalation policies, phone calls or SMS.
- Nothing faster than one-minute checks, and no heartbeat, cron, TCP or mail checks.
- Better Stack checks from several locations; SiteOps from one, with a Cloudflare re-check on failure.
- Better Stack's Playwright checks run full scripts; SiteOps journeys are declarative steps only.
For agencies
Every client, one place to look.
01 / 03
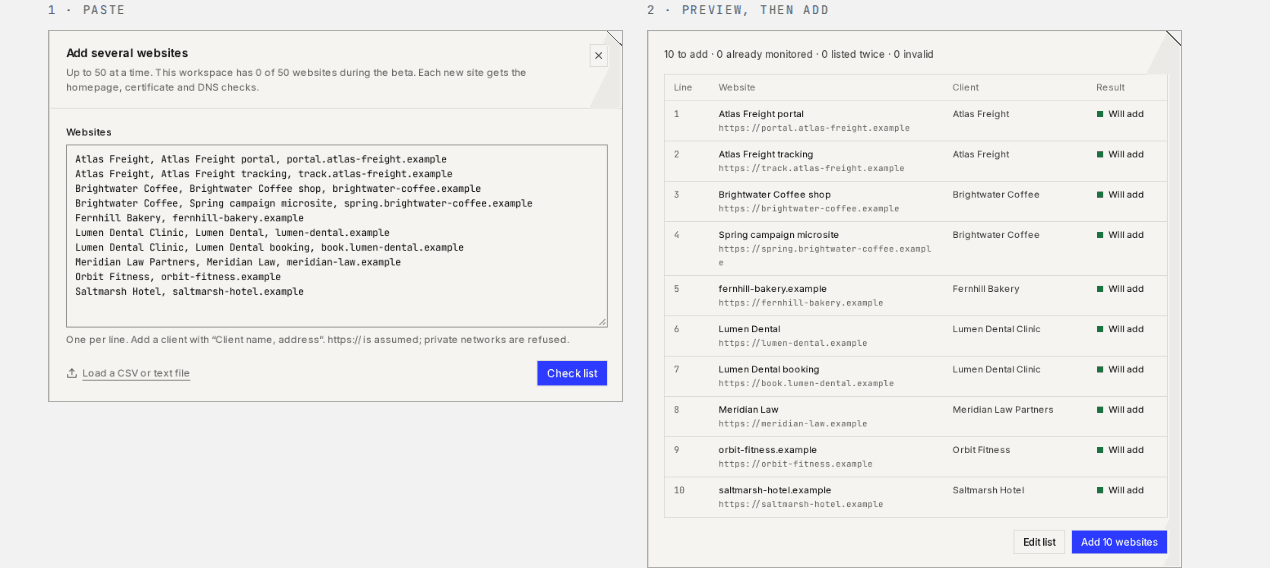
Add every client at once
Paste up to 50 addresses, or a CSV with client names. You see what will be added before anything is.
02 / 03
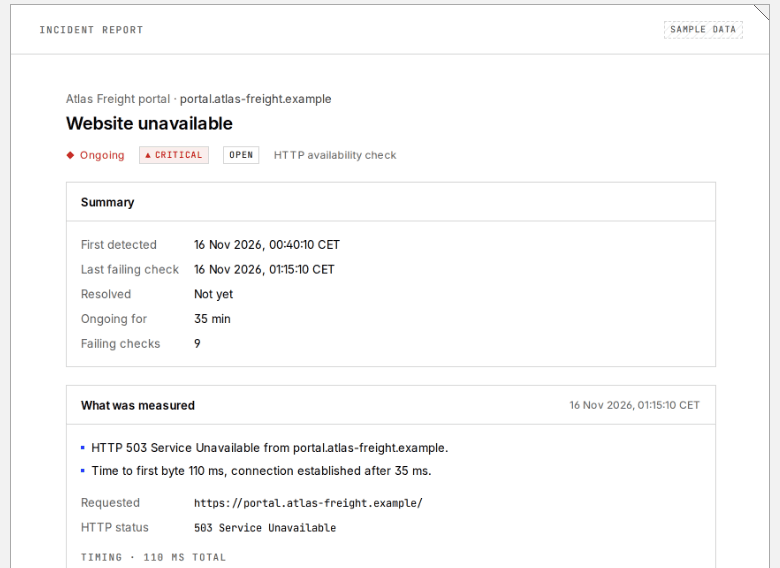
A link you can send the client
A read-only page for one incident: what was measured, when, and for how long. No internals, revocable at any time.
03 / 03
Monthly report, sent for you
Availability, response times, incidents and expiring certificates per client, emailed on the day you choose under your agency's name.
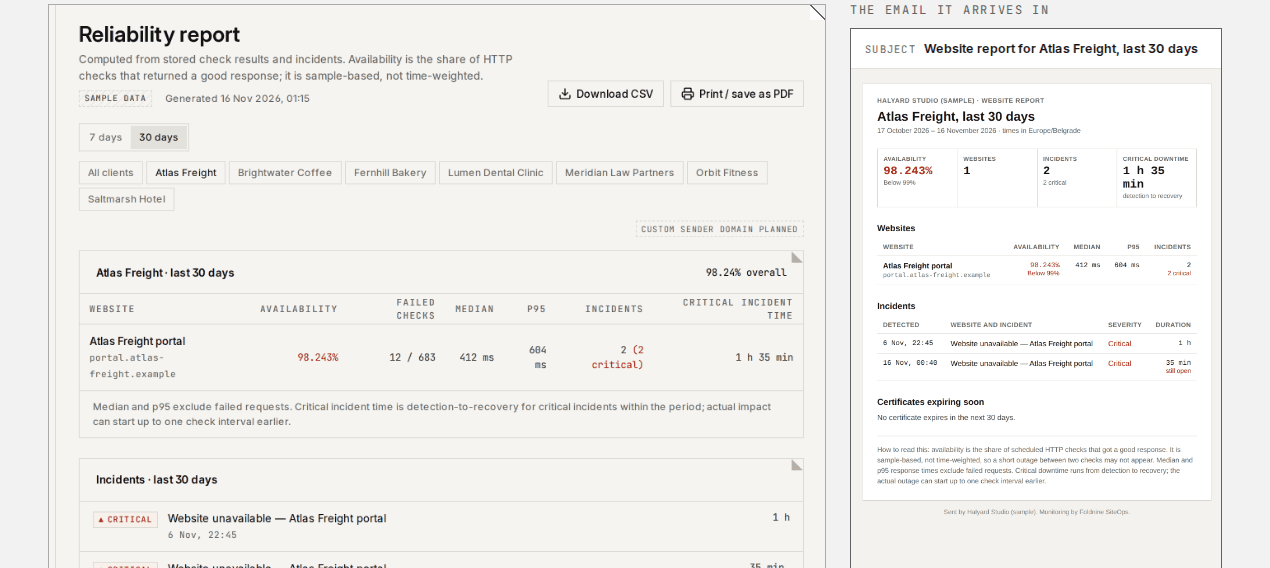
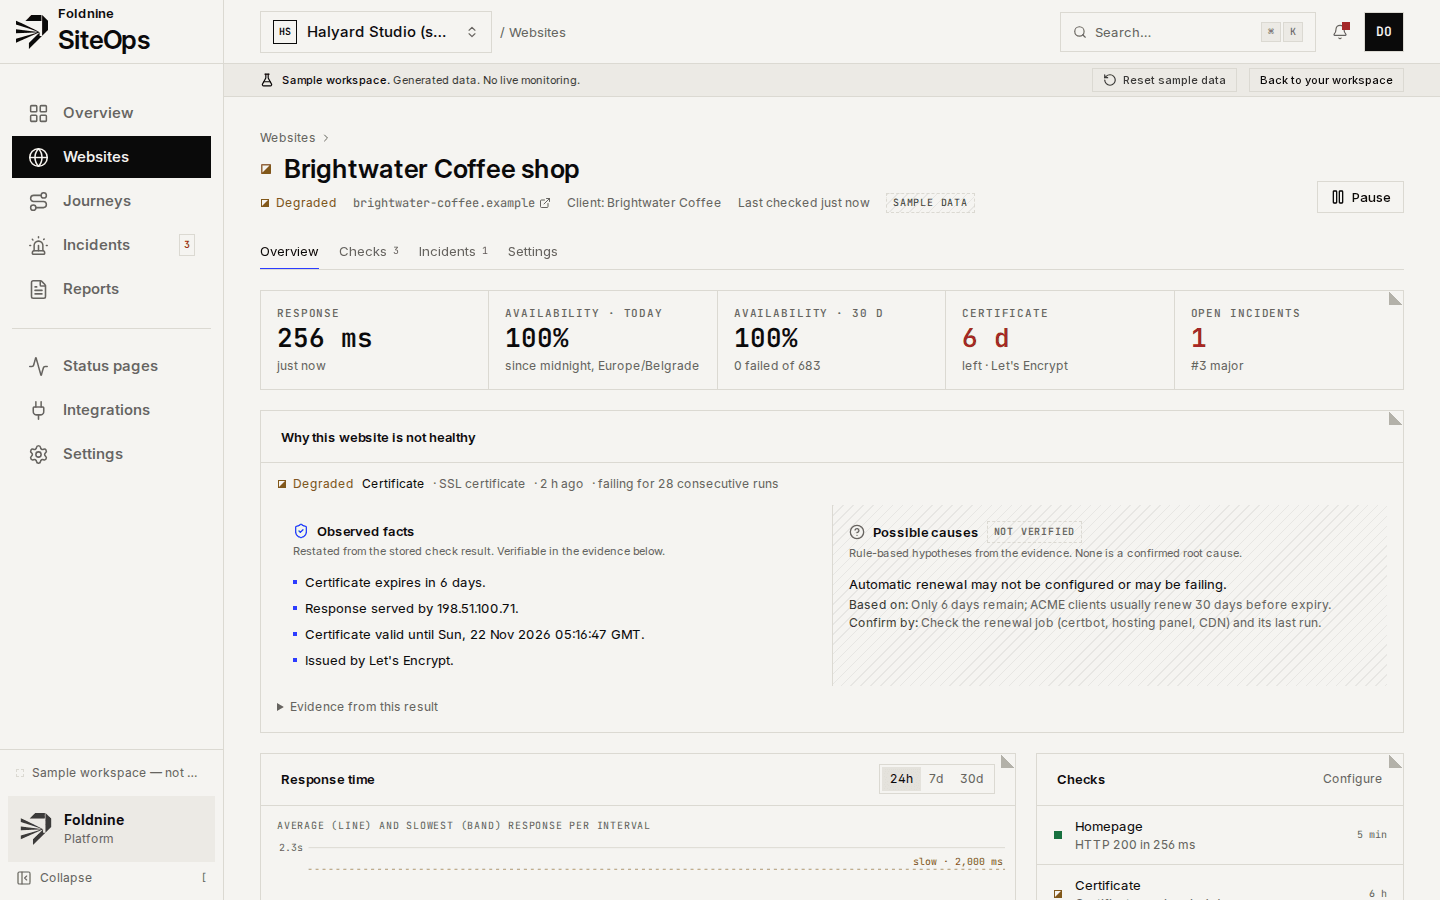
Screens from the built-in sample workspace: a fictional agency on reserved .example domains.
Questions
Frequently asked
- Is SiteOps cheaper than Better Stack for agencies?
- Usually, once you need white-label or more than a few sites. SiteOps Agency is €69 a month for 100 sites, white-label status pages and reports included. On Better Stack, a responder seat is $34 a month, every 50 monitors beyond the first 10 are $25 a month, and a white-label status page is $250 a month per page.
- Does SiteOps have on-call scheduling?
- No. SiteOps alerts by email, Telegram, Slack and webhook, with a minimum severity per channel. If you need rotations and phone escalation, Better Stack does that, and the SiteOps webhook can feed a tool that pages people.
- Can SiteOps run Playwright scripts?
- Not arbitrary scripts. Browser journeys are declarative steps (open, click, fill, wait, expect text or URL, screenshot), up to 25 steps, run in a fresh Chromium. That covers logins and forms without running customer code.
- Is there a free plan?
- Yes: 5 websites, checks every 5 minutes, email alerts, no card. Better Stack's free tier has 10 monitors at 3-minute checks.